
About Dune Science
Independent technical assessment of frontier AI safety cases
Our Mission
Dune Science’s mission is to strengthen collective understanding of the safety of today’s frontier AI models through independent, technical assessment of their safety cases.
As AI systems become more capable, frontier developers have begun to rest their training and deployment decisions on safety cases [1, 2, 3]: structured arguments that a system is safe enough for a given use [4, 5].
Yet, unlike in more mature safety-critical fields such as nuclear power and aviation, these safety cases are not consistently assessed by an independent third party: they are largely judged by the same developers who write them [4, 5]. And none of the published safety cases, whether written by developers or by researchers, comes with a realistic implementation open to the public, so outsiders have no way of producing their own evidence that the arguments actually hold in practice.
We aim to bridge those gaps. As an independent third party, we build faithful, realistic implementations of published safety cases, test their claims through experiments, and publish reports that show where their arguments hold and where they break.
We carry out this work with scientific rigor, technical excellence and full transparency, releasing every report, implementation and dataset we produce. In doing so, we hope to equip the public with the evidence and tools it needs to shape how increasingly powerful AI systems, and eventually superintelligent ones, are trained and deployed safely.
What we do
For every safety case we assess, we follow the same three steps.
- Implement. We build a faithful version of the safety case in a realistic setting: the models, the deployment environment, the safeguards and the evaluations its argument relies on.
- Test. We break the argument down into its claims and assumptions, and design experiments that try to falsify each one, including under conditions its authors did not consider.
- Publish. We release a report on what held, what failed and under which conditions, together with the full implementation, so that anyone can rerun our experiments, extend them or apply them to their own models.
Our reports are meant to inform policymakers, the public and frontier AI developers about how far the safety arguments behind today's models can be trusted. Our open implementations give researchers a shared foundation to build on, helping advance the science of how to make AI systems safer.
Team
-
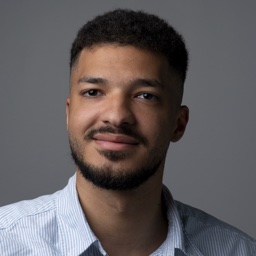 Aton Kamanda
Founder
Research Engineer, LawZero
-
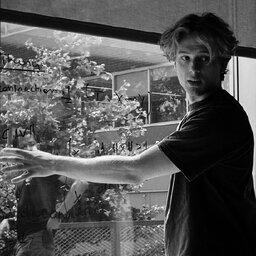 Lucas Maes
Founder
PhD student, Mila and UdeM
References
- OpenAI (2026). Towards safety cases for frontier AI training. openai.com
- Anthropic (2025). Anthropic’s Summer 2025 Pilot Sabotage Risk Report. alignment.anthropic.com
- Phuong, M., Zimmermann, R. S., Wang, Z., Lindner, D., Krakovna, V., Cogan, S., Dafoe, A., Ho, L., & Shah, R. (2025). Evaluating Frontier Models for Stealth and Situational Awareness. arXiv:2505.01420
- Clymer, J., Gabrieli, N., Krueger, D., & Larsen, T. (2024). Safety Cases: How to Justify the Safety of Advanced AI Systems. arXiv:2403.10462
- Hilton, B., Buhl, M. D., Korbak, T., & Irving, G. (2025). Safety Cases: A Scalable Approach to Frontier AI Safety. arXiv:2503.04744